 22M
- Released
- 1y ago
- Size
- 7.8Bparameters
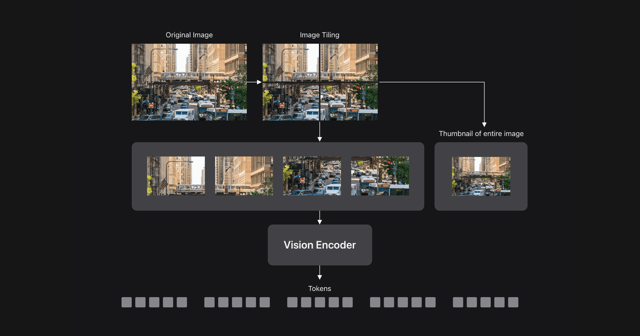
Largest FastVLM vision language model, with the highest accuracy of the family.
- Multimodal model
- Open weights · 7.8B
- Accepts images
How it compares
Frequently asked questions
Running locally
By our estimate, FastVLM 7B needs about 5.9 GB at Q4, 10 GB at Q8 and 18.4 GB at FP16 of VRAM. That covers the weights plus headroom for a short context, and longer contexts need more.
Yes, by our estimates FastVLM 7B fits on an 8 GB GPU at Q4 (about 5.9 GB) and at higher precision on larger cards.
Yes, a Mac with at least 8 GB of unified memory should run FastVLM 7B at Q4, which needs an estimated 5.9 GB. This assumes macOS gives the GPU about 75% of unified memory.
Privacy and data
Yes, FastVLM 7B has open weights, so you can run it on your own hardware and keep prompts on your own machines.
Capabilities and specs
Yes, FastVLM 7B accepts images as input alongside text.
Quality and benchmarks
Similar models from other labs include Llama Prompt Guard 2 22M (Meta), Llama Prompt Guard 2 86M (Meta) and Qwen3 8B (Alibaba). They are the closest matches by kind and release date.
Llama Prompt Guard 2 22MFastVLM 7B vs Llama Prompt Guard 2 22MLlama Prompt Guard 2 86MFastVLM 7B vs Llama Prompt Guard 2 86MQwen3 8BFastVLM 7B vs Qwen3 8B
Licensing and access
FastVLM 7B has open weights under the apple-amlr license, so you can download and run it yourself.
The FastVLM 7B weights are on Hugging Face at apple/FastVLM-7B.
Basics
FastVLM 7B was made by Apple. It was released on May 7, 2025.
Yes, FastVLM 7B has open weights, so you can run it on your own hardware without API fees.
Generated from Vertical Tabs data, updated November 3, 2026.
Discussion
No comments yet
Be the first to share your thoughts.