- Context
- 33Ktokens
- Released
- 8mo ago
- Size
- 24Bparameters
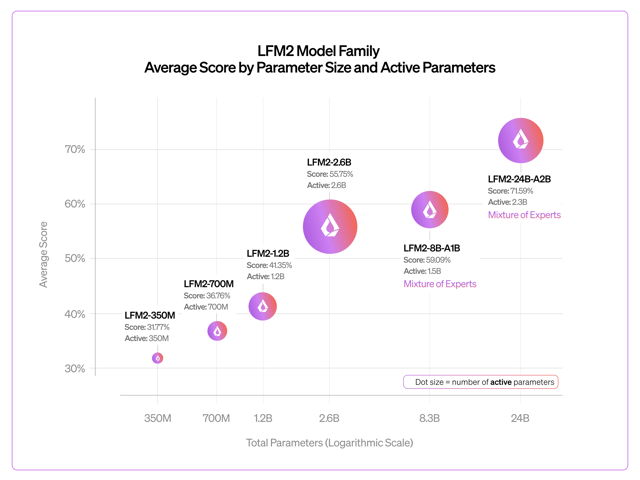
LFM2-24B-A2B is Liquid AI's largest LFM2 model, a sparse Mixture-of-Experts release presented as showing that its hybrid LFM2 architecture, shared with LFM2-8B-A1B, scales to larger sizes. Its headline claim is efficiency: with only 2 billion parameters active per token, Liquid AI says the model keeps per-token compute and memory cost low enough to fit in 32 GB of RAM for laptop and edge deployment. It is built for on-device agentic tool use, document summarization, customer support and local retrieval-augmented generation, though the maker says it is not optimized for coding.
How it compares
Additional source evidence
- Source model
- liquid/lfm2-24b-a2b
- Source family
- liquid
- Last updated
- 2026-02-24
- Model context
- 33K
- Model output limit
- 33K
- Open weights
- Yes
- File attachments
- No
- Reasoning
- No
- Tool calling
- Yes
- Temperature control
- Yes
Downloadable weights
Complete source record (JSON)
{
  "id": "liquid/lfm2-24b-a2b",
  "name": "LFM2 24B A2B",
  "description": "Efficient open Liquid MoE instruct model for on-device chat and tool calling",
  "family": "liquid",
  "last_updated": "2026-02-24",
  "attachment": false,
  "reasoning": false,
  "tool_call": true,
  "temperature": true,
  "modalities": {
    "input": [
      "text"
    ],
    "output": [
      "text"
    ]
  },
  "limit": {
    "context": 32768,
    "output": 32768
  },
  "release_date": "2026-02-24",
  "open_weights": true,
  "license": "LFM Open License v1.0",
  "weights": [
    {
      "label": "Hugging Face",
      "url": "https://huggingface.co/LiquidAI/LFM2-24B-A2B"
    }
  ]
}
Frequently asked questions
Running locally
LFM2 24B A2B needs an estimated 17.2 GB of VRAM at Q4, 29.8 GB at Q8 and 55.7 GB at FP16. These figures are estimates from the 24B parameter count, covering weights plus about 15% and 0.5 GB for a short context.
Yes, LFM2 24B A2B fits on a 24 GB GPU at Q4 (estimated 17.2 GB). It does not fit on a 16 GB, 12 GB or 8 GB GPU at Q4, Q8 or FP16, according to the same estimates.
Yes, LFM2 24B A2B can run on a Mac with unified memory at Q4, which needs an estimated 17.2 GB. This assumes macOS lets the GPU use about 75% of unified memory. The smallest common Mac memory size that fits Q4 is 24 GB (estimate).
Privacy and data
Yes, LFM2 24B A2B has open weights, so you can self-host it for full control of your data.
Capabilities and specs
The context window of LFM2 24B A2B is 33K tokens (32,768). Its maximum output is also 33K tokens (32,768).
No, LFM2 24B A2B only accepts text. Images, audio, video and PDFs are not supported inputs.
Yes, LFM2 24B A2B supports tool calling (function calling).
No, LFM2 24B A2B does not support a reasoning or thinking mode.
Quality and benchmarks
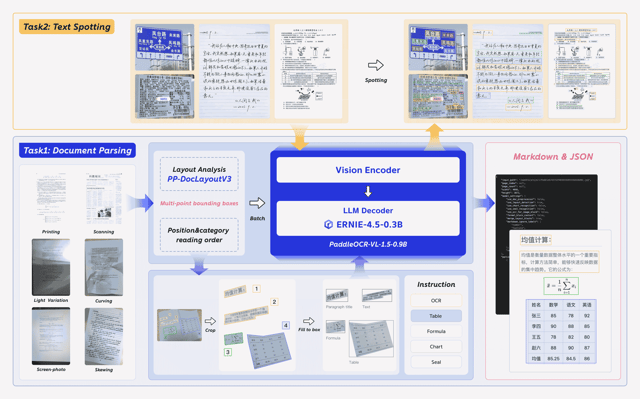
The closest alternatives to LFM2 24B A2B, matched on model kind and release date with no comparable price, are Olmo Hybrid 7B Instruct by Ai2, Olmo Hybrid 7B Think by Ai2 and PaddleOCR-VL 1.5 by Baidu.
Olmo Hybrid 7B InstructLFM2 24B A2B vs Olmo Hybrid 7B InstructOlmo Hybrid 7B ThinkLFM2 24B A2B vs Olmo Hybrid 7B ThinkPaddleOCR-VL 1.5LFM2 24B A2B vs PaddleOCR-VL 1.5
Licensing and access
LFM2 24B A2B is open weights. Its license is the LFM Open License v1.0.
You can download the LFM2 24B A2B weights from the Hugging Face repository LiquidAI/LFM2-24B-A2B.
Basics
LFM2 24B A2B was made by Liquid AI and released on February 24, 2026.
Yes, LFM2 24B A2B is open weights, so it can be used for free.
Generated from Vertical Tabs data, updated November 12, 2026.
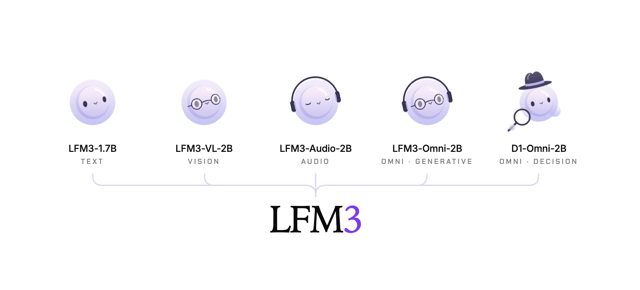
More in Liquid
Discussion
No comments yet
Be the first to share your thoughts.