 Qwen3.5 9B Base
 Ministral 14B
- Context
- 131Ktokens
- Released
- 1y ago
- Size
- 5.6Bparameters
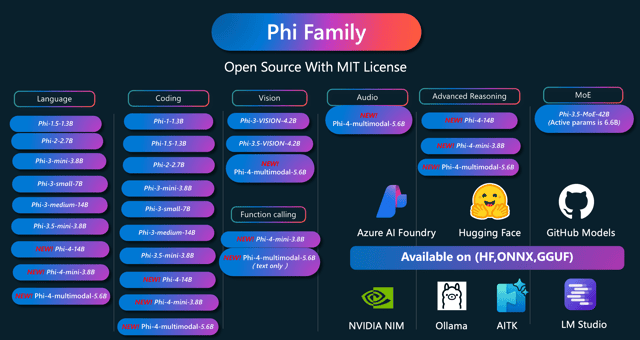
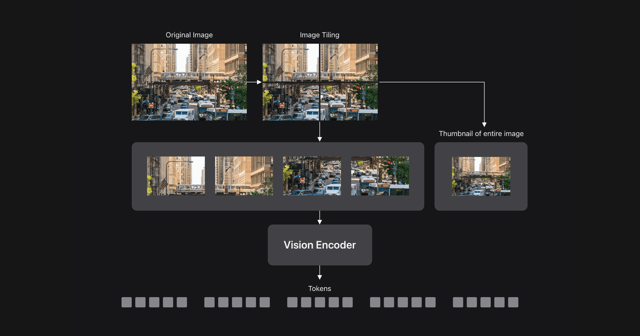
Phi-4-multimodal-instruct is a lightweight open multimodal model from Microsoft that builds on the language, vision, and speech research and datasets used for the Phi-3.5 and 4.0 models. Its release notes highlight a single open model trained across text, vision, and audio, processing those inputs in one neural network rather than the two-model pipeline previously needed. It is intended for broad commercial and research use, including math and logic reasoning, function and tool calling, image understanding, OCR, and speech recognition and translation.
- Multimodal model
- Open weights · 5.6B
- Accepts images, audio
- Tools
How it compares
Size class
Small5.6BAn open-weight model of 5 to 25 billion parameters, the size that runs on a single consumer GPU.
Open models of a similar size from other labs
Vs. your stack
Add the models you use to see how this one compares.
Sign inAdditional source evidence
- Source model
- microsoft/phi-4-multimodal-instruct
- Source family
- phi
- Last updated
- 2025-02-26
- Knowledge cutoff
- 2024-06
- Model context
- 131K
- Model output limit
- 131K
- Open weights
- Yes
- File attachments
- Yes
- Reasoning
- No
- Tool calling
- Yes
- Temperature control
- Yes
Downloadable weights
Complete source record (JSON)
{
  "id": "microsoft/phi-4-multimodal-instruct",
  "name": "Phi-4-multimodal-instruct",
  "description": "Compact Microsoft multimodal model for text, image, and speech understanding",
  "family": "phi",
  "last_updated": "2025-02-26",
  "knowledge": "2024-06",
  "attachment": true,
  "reasoning": false,
  "tool_call": true,
  "temperature": true,
  "modalities": {
    "input": [
      "text",
      "image",
      "audio"
    ],
    "output": [
      "text"
    ]
  },
  "limit": {
    "context": 131072,
    "output": 131072
  },
  "release_date": "2025-02-26",
  "open_weights": true,
  "license": "MIT",
  "weights": [
    {
      "label": "Hugging Face",
      "url": "https://huggingface.co/microsoft/Phi-4-multimodal-instruct"
    }
  ]
}
Frequently asked questions
Running locally
At Q4 it needs an estimated 4.4 GB, at Q8 an estimated 7.3 GB and at FP16 an estimated 13.3 GB. These estimates come from the 5.6B parameter count, weights plus about 15% and 0.5 GB for a short context.
Yes. A 24 GB and a 16 GB GPU fit at FP16 (estimated 13.3 GB), and a 12 GB and an 8 GB GPU fit at Q8 (estimated 7.3 GB).
Yes, at Q4 it needs an estimated 4.4 GB. Assuming macOS lets the GPU use about 75% of unified memory, the smallest common Mac memory size that fits is 8 GB.
Privacy and data
Yes, it has open weights, so you can self-host it for full control of your data.
Capabilities and specs
The context window is 131K tokens (131,072), and the maximum output is also 131K tokens (131,072).
It reads text, image and audio. Video and PDFs are not among its input modalities.
Yes, tool calling (function calling) is supported.
No, a reasoning or thinking mode is not supported.
The knowledge cutoff is 2024-06.
Quality and benchmarks
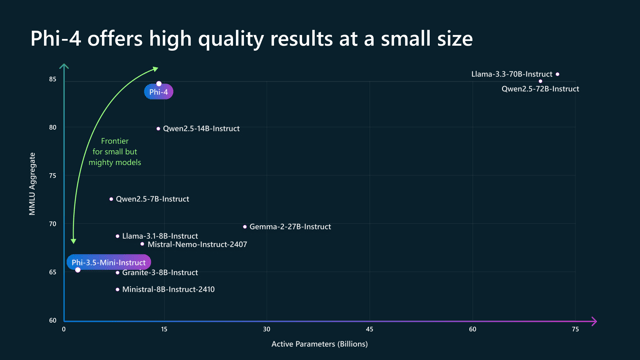
olmOCR by Ai2, Command R7B Arabic by Cohere and QwQ 32B by Alibaba. They are matched on model kind and release date, with no comparable price.
olmOCRPhi-4-multimodal-instruct vs olmOCRCommand R7B ArabicPhi-4-multimodal-instruct vs Command R7B ArabicQwQ 32BPhi-4-multimodal-instruct vs QwQ 32B
Versions and lineage
Phi-4-multimodal-instruct has a 131K token (131,072) context, while Phi 4 has 16K tokens (16,384). Phi-4-multimodal-instruct was released February 26, 2025, and Phi 4 on December 12, 2024. Phi 4 price is $0.07 input and $0.14 output per 1M tokens.
Licensing and access
It is open weights, not fully open source. The license is MIT.
Yes, the MIT license is a permissive license that allows commercial use.
From the Hugging Face repository microsoft/Phi-4-multimodal-instruct.
Basics
Microsoft made Phi-4-multimodal-instruct. It was released February 26, 2025.
Yes, it has open weights.
Generated from Vertical Tabs data, updated November 10, 2026.
Discussion
No comments yet
Be the first to share your thoughts.