 1.7B
- input
- $0.08
- cached
- $0.04
- output
- $0.13
- Context
- 262Ktokens
- Listed
- 3w ago
- Size
- 9Bparameters
Cost/1M tokens
Language model from PrismML, listed on OpenRouter on October 16, 2026.
- Multimodal model
- Open weights · 9B
- Accepts images
- Reasoning
- Tools
- Structured output
How it compares
Family tree
Models trained from one another, as their makers describe it.
 Qwen3.5-9BQwen · 2026
Frequently asked questions
Running locally
Ternary Bonsai 2 9B needs an estimated 6.8 GB at Q4, 11.5 GB at Q8 and 21.2 GB at FP16. These figures are estimates from the parameter count, covering weights plus about 15% and 0.5 GB for a short context.
Yes. A 24 GB GPU fits at FP16 (estimated 21.2 GB), a 16 GB or 12 GB GPU fits at Q8 (estimated 11.5 GB), and an 8 GB GPU fits at Q4 (estimated 6.8 GB).
Yes. Q4 needs an estimated 6.8 GB, and assuming macOS lets the GPU use about 75% of unified memory, the smallest common Mac memory size that fits Q4 is 16 GB.
API and pricing
Input costs $0.08 per 1M tokens and output costs $0.13 per 1M tokens. There is 1 paid provider tracked.
Yes, it supports prompt caching. Cached input costs $0.04 per 1M tokens versus $0.08 uncached, a 50% discount.
A typical request with 10,000 input tokens and 1,000 output tokens costs $0.00093 at the cheapest provider, Darkbloom.
Yes, tracked endpoints were reliable last day. 1 endpoint had uptime data, 1 was at 99% uptime or better, and the best uptime was 100.0%, by Darkbloom.
Privacy and data
Yes. Ternary Bonsai 2 9B has open weights, so you can self-host it for full control of your data.
Capabilities and specs
The context window is 262K tokens (262,144) and the maximum output is 66K tokens (65,536).
Ternary Bonsai 2 9B accepts text and image input. Audio, video and PDF are not listed as supported input modalities.
Yes, tool calling (function calling) is supported.
Yes, structured output (JSON schema or JSON mode) is supported.
Yes, a reasoning mode is supported and exposed by 1 of 1 tracked providers. It is not always on, and no provider offers an effort setting (reasoning_effort).
Quality and benchmarks
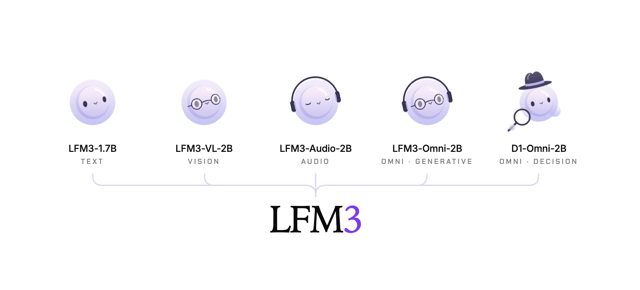
Comparable alternatives are LFM3-1.7B by Liquid AI at $0.11 per 1M tokens blended, Ling 3.0 Flash VL by InclusionAI at $0.09, and Nemotron 3.5 Lightning by NVIDIA at $0.1025. They are matched on model kind, blended price and release date.
LFM3-1.7BTernary Bonsai 2 9B vs LFM3-1.7BLing 3.0 Flash VLTernary Bonsai 2 9B vs Ling 3.0 Flash VLNemotron 3.5 LightningTernary Bonsai 2 9B vs Nemotron 3.5 Lightning
Versions and lineage
Ternary Bonsai 2 9B is a variant of Qwen3.5-9B.
Licensing and access
Ternary Bonsai 2 9B is open weights.
The weights are available from the Hugging Face repository prism-ml/Ternary-Bonsai-2-9B-gguf.
Basics
Ternary Bonsai 2 9B was made by PrismML and was first listed on OpenRouter on October 16, 2026.
No. The listed API price is $0.08 input and $0.13 output per 1M tokens, though the model itself has open weights.
Generated from Vertical Tabs data, updated November 11, 2026.
Discussion
No comments yet
Be the first to share your thoughts.